AI AtlasTHE AI DIRECTORY

THE ENGINES BEHIND AI

AI processors.
Know the capacity.

Explore CPUs, GPUs, TPUs, NPUs and edge AI chips. See who makes them, what their specifications mean and where they fit in an AI workflow.

Explore 9 processors ↓

CPU

General computing, data preparation and inference.

GPU

Parallel computation for training and inference.

TPU

Google-designed tensor acceleration in the cloud.

NPU / SoC

Integrated, efficient on-device AI processing.

Edge AI

Compact devices for robots, cameras and local inference.

Compare like for like. TOPS means trillion operations per second; TFLOPS means trillion floating-point operations per second. Precision (INT8, FP4, BF16), sparsity, software and power limits change results. These examples are not a performance ranking or an exhaustive list of the newest chips. Memory needs also depend on model size, quantization, context and runtime overhead. Specifications checked 20 Oct 2026; follow each official source for updates.

9 processors

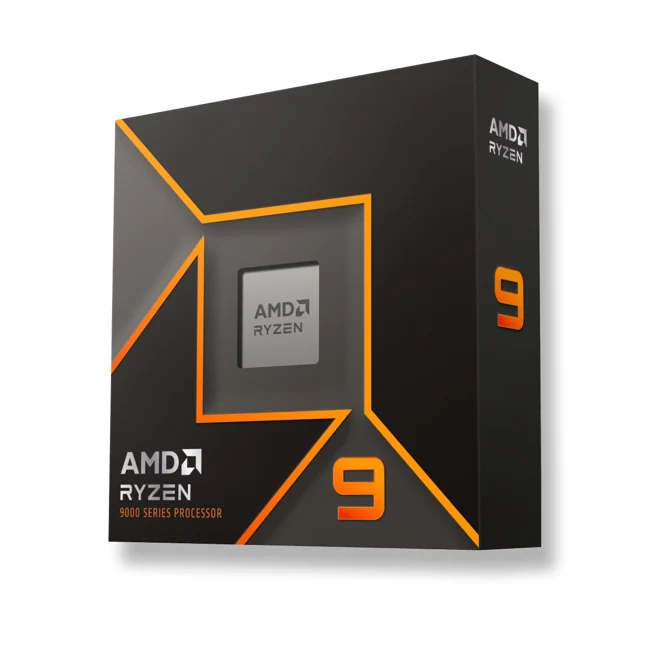
AMD Ryzen 9 9950X product image
Manufacturer product image
Image source ↗
CPU · AMD

AMD Ryzen 9 9950X

Advanced Micro Devices, Inc.
Designs Ryzen CPUs, Ryzen AI processors and Instinct GPU accelerators. Manufacturer website ↗

Architecture
Zen 5; desktop AM5
Memory capacity
System DDR5 RAM; installed capacity depends on motherboard
Compute / bandwidth
16 CPU cores / 32 threads; boost up to 5.7 GHz
AI use
Data preparation, development and CPU inference. Pair with a compatible GPU for accelerated training.
Software
x86-64 CPU frameworks; GPU software depends on the added GPU

CPU cores and clock speed are not GPU AI TOPS. No dedicated Ryzen AI NPU in this model.
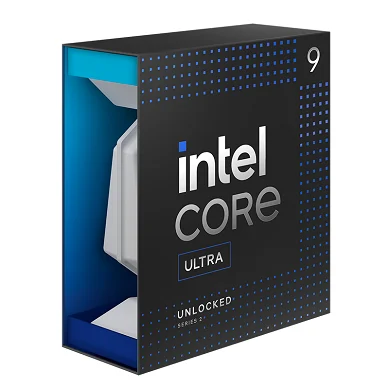
Intel Core Ultra 9 285K retail packaging
Intel retail packaging
Image source ↗
CPU · Intel

Intel Core Ultra 9 285K

Intel Corporation
Develops Core and Xeon CPUs and integrated AI acceleration technologies. Manufacturer website ↗

Architecture
Core Ultra 200S; desktop
Memory capacity
System DDR5 RAM; motherboard and configuration dependent
Compute / bandwidth
24 CPU cores (8 performance + 16 efficient); NPU 13 peak INT8 TOPS
AI use
Desktop AI development, preprocessing and supported on-device AI tasks.
Software
Intel OpenVINO; x86-64 frameworks

The 13 TOPS figure belongs to the integrated NPU, not the CPU or a discrete GPU.
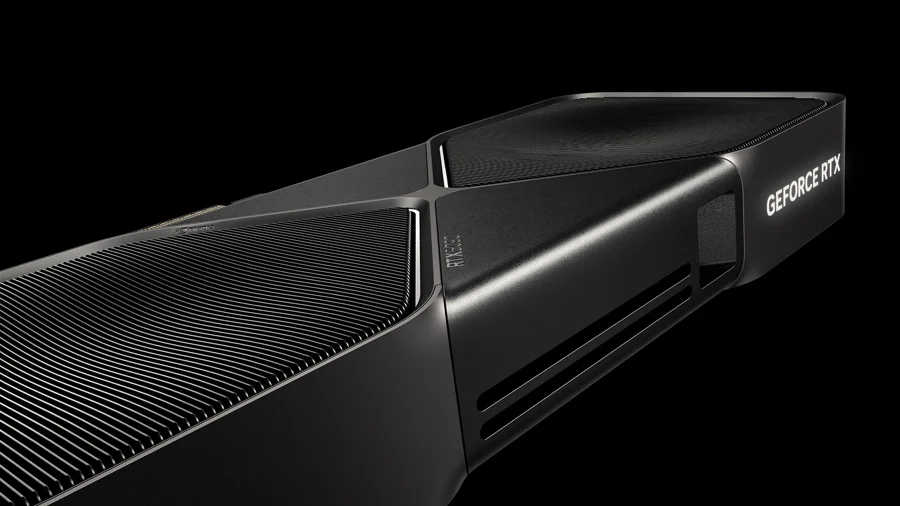
NVIDIA GeForce RTX 5090 graphics card
Manufacturer product image
Image source ↗
GPU · NVIDIA

NVIDIA GeForce RTX 5090

NVIDIA Corporation
Designs GeForce GPUs, data-center accelerators and Jetson edge AI platforms. Manufacturer website ↗

Architecture
Blackwell; desktop graphics card
Memory capacity
32 GB dedicated GDDR7 VRAM
Compute / bandwidth
3,352 advertised AI TOPS (peak FP4 with sparsity)
AI use
Local model inference, image generation and compatible model fine-tuning.
Software
CUDA, TensorRT; compatible PyTorch builds

Desktop specification. Laptop RTX 5090 specifications differ. Peak sparse FP4 is not directly comparable with dense INT8 or BF16.
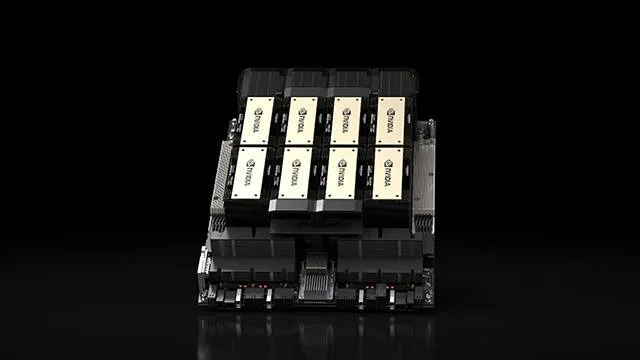
NVIDIA HGX H200 platform with H200 accelerators
HGX H200 platform · manufacturer image
Image source ↗
GPU · NVIDIA

NVIDIA H200

NVIDIA Corporation
Designs GeForce GPUs, data-center accelerators and Jetson edge AI platforms. Manufacturer website ↗

Architecture
Hopper; data-center accelerator
Memory capacity
141 GB HBM3e per GPU
Compute / bandwidth
4.8 TB/s memory bandwidth
AI use
Server-based large-model inference and training.
Software
CUDA, TensorRT-LLM, NVIDIA AI Enterprise

Requires a supported server platform. Bandwidth measures data movement, not operations per second.
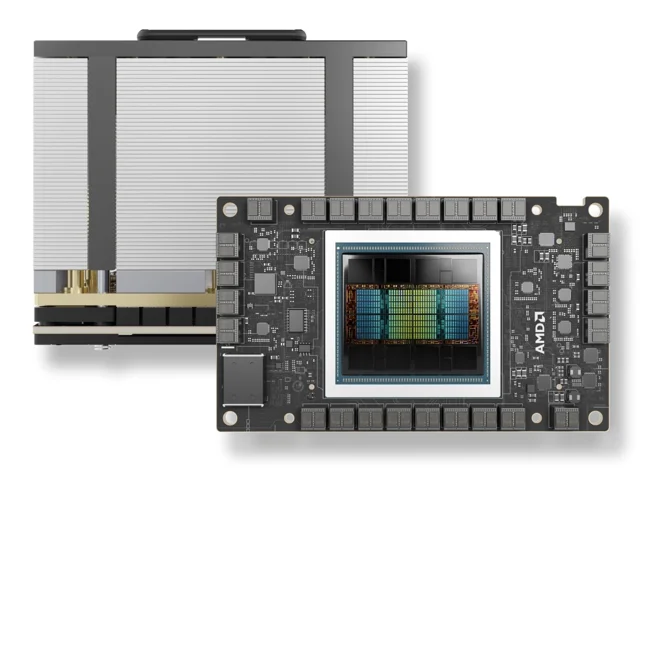
AMD Instinct MI300X accelerator
Manufacturer product image
Image source ↗
GPU · AMD

AMD Instinct MI300X

Advanced Micro Devices, Inc.
Designs Ryzen CPUs, Ryzen AI processors and Instinct GPU accelerators. Manufacturer website ↗

Architecture
CDNA 3; data-center accelerator
Memory capacity
192 GB HBM3 per accelerator
Compute / bandwidth
Up to 5.3 TB/s memory bandwidth
AI use
Large-model inference and training on compatible servers.
Software
ROCm; supported PyTorch builds

The capacity is for one accelerator, not the total memory of an eight-GPU platform. Check ROCm model and operating-system support.
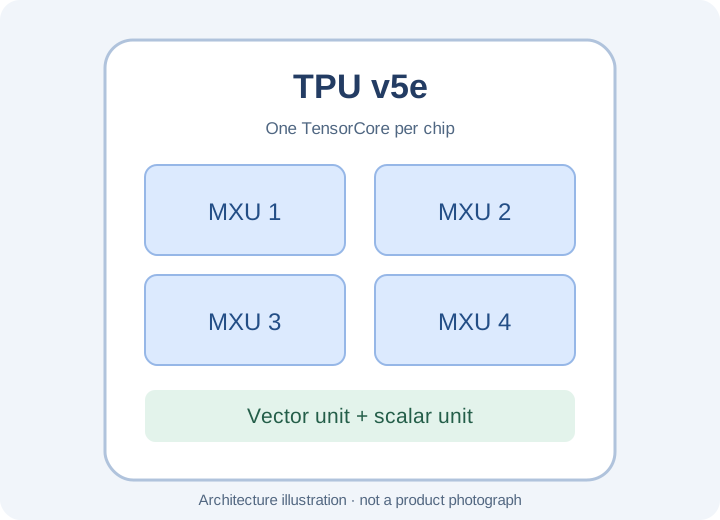
TPU v5e architecture showing four matrix units and vector and scalar units
AI Atlas architecture illustration · not a product photo
Image source ↗
TPU · Google

Google Cloud TPU v5e

Google
Designs Tensor Processing Units and offers them through Google Cloud. Manufacturer website ↗

Architecture
Tensor Processing Unit; cloud accelerator
Memory capacity
16 GB HBM per chip
Compute / bandwidth
197 peak BF16 TFLOPS per chip
AI use
Cloud model training and inference with TPU-compatible code.
Software
JAX, TensorFlow and PyTorch/XLA

Cloud service rather than a desktop add-in card. Per-chip figures differ from multi-chip slice or pod totals.
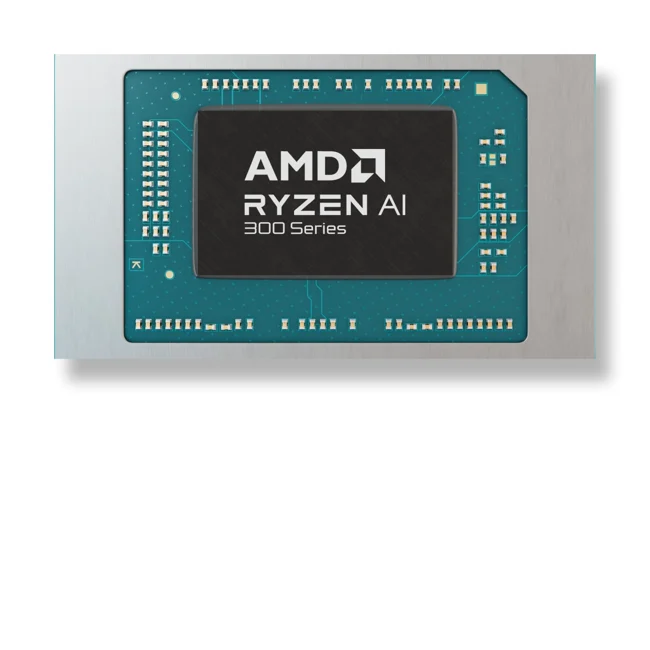
AMD Ryzen AI 300 series manufacturer illustration
Ryzen AI 300 series · manufacturer illustration
Image source ↗
NPU / SoC · AMD

AMD Ryzen AI 9 HX 370

Advanced Micro Devices, Inc.
Designs Ryzen CPUs, Ryzen AI processors and Instinct GPU accelerators. Manufacturer website ↗

Architecture
Zen 5 / Zen 5c CPU; XDNA 2 NPU; Radeon 890M GPU
Memory capacity
Shared system memory; laptop configuration dependent
Compute / bandwidth
12 CPU cores; NPU up to 50 TOPS
AI use
Power-efficient on-device AI features and supported inference workloads.
Software
AMD Ryzen AI Software; supported ONNX models

50 TOPS is the NPU rating. Integrated graphics shares system RAM and does not have separate dedicated VRAM.
Apple M4 chip manufacturer illustration
Apple M4 · manufacturer illustration
Image source ↗
NPU / SoC · Apple

Apple M4

Apple Inc.
Designs Apple silicon combining CPU, GPU and Neural Engine in one system on a chip. Manufacturer website ↗

Architecture
Apple silicon; CPU + GPU + Neural Engine
Memory capacity
Unified memory shared by CPU and GPU; device configuration dependent
Compute / bandwidth
Up to 10 CPU cores; 10 GPU cores; Neural Engine 38 trillion operations/s
AI use
Local inference, AI-assisted creative work and supported Apple-device applications.
Software
Metal, Core ML; MLX on supported Macs

Base M4 example; M4 Pro and Max are different chips. Neural Engine performance does not represent GPU performance.
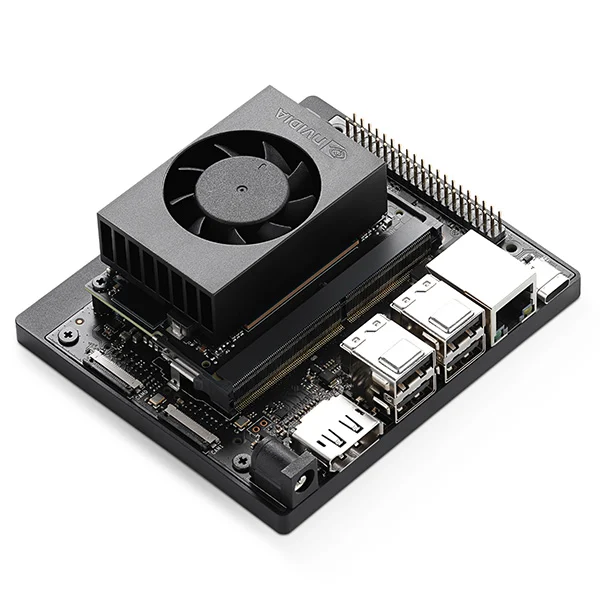
NVIDIA Jetson Orin Nano Super Developer Kit
Manufacturer product image
Image source ↗
Edge AI · NVIDIA

NVIDIA Jetson Orin Nano Super

NVIDIA Corporation
Designs GeForce GPUs, data-center accelerators and Jetson edge AI platforms. Manufacturer website ↗

Architecture
Ampere GPU + Arm CPU; developer kit
Memory capacity
8 GB shared LPDDR5 memory
Compute / bandwidth
Up to 67 sparse INT8 TOPS; 102 GB/s memory bandwidth
AI use
Robotics, camera inference and small edge AI applications.
Software
JetPack, CUDA, TensorRT

Super performance requires the supported software and power mode. Shared memory also serves the operating system.

Learn by watching. Each processor has a YouTube search link directly below its specifications. These open model-specific tutorials and explanations; individual videos have not been selected or endorsed.